
Do Your Prompts Produce Accurate Lists?
Presented by 
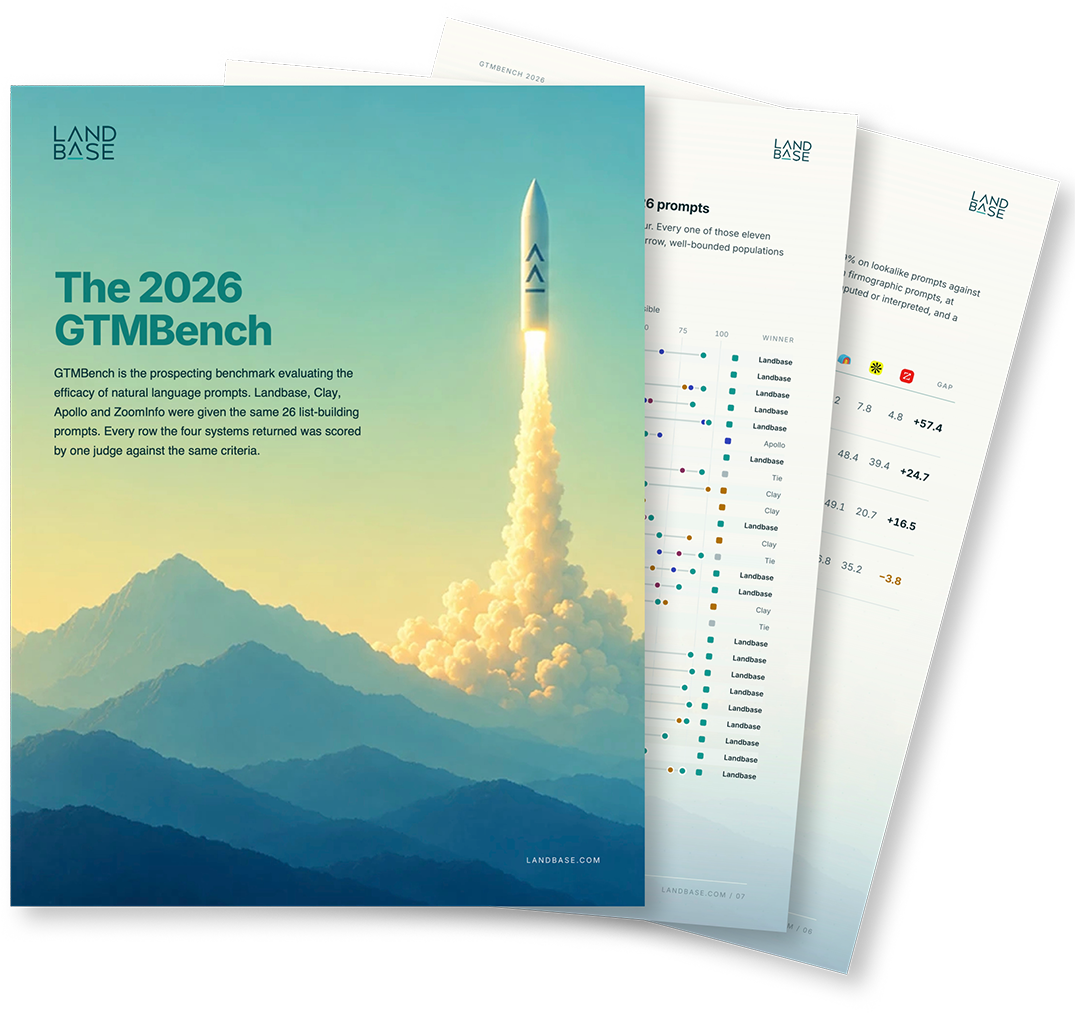
The 2026 GTMBench scores Landbase, Clay, Apollo and ZoomInfo on one question: how well can the platform understand natural-language prompts and provide an accurate list? This report breaks it down by prompt family, by prompt, and by vendor.
26 Prompts Tested.
4 Key Findings Discovered.
-
3 of 4
Agents lead three of four prompt families.
Filters win only where the prompt names attributes the vendor already stores.
-
18 of 26
Landbase returns the most precise list.
76.7% of its rows meet every criterion, against 47.9% for the next vendor.
-
3 prompts
Two of the four vendors can’t express three prompts.
Clay and ZoomInfo declined the same three. Landbase scored 96.1% or better on all of them.
-
134 seconds
Landbase is the slowest of the four systems.
It checks every company against every condition before it returns a row.